"A biography on Wikipedia might not be intended as a prize, but nobody knows its value like the people who’ve had one and then lost it."
Duncan Fyfe for WIRED: https://www.wired.com/story/the-tragedy-of-losing-your-wikipedia-page/
Public posts with this hashtag.
"A biography on Wikipedia might not be intended as a prize, but nobody knows its value like the people who’ve had one and then lost it."
Duncan Fyfe for WIRED: https://www.wired.com/story/the-tragedy-of-losing-your-wikipedia-page/
I like this new design.
https://github.com/cedricbonhomme/newspipe
#RSS #Atom #OpenSource #Python #SelfHosting #Web #Indiedev #News
AI Is Unearthing Internet’s Hidden Flaws—and More Outages May Follow, by @straits_times:
#meme #php #cybersecurity #security #cybercrime #hack #web #www #server #patch #admin #administrator #Software #vulnerability #bug #internet #online


SimCity, but with Permits (petercai.com)
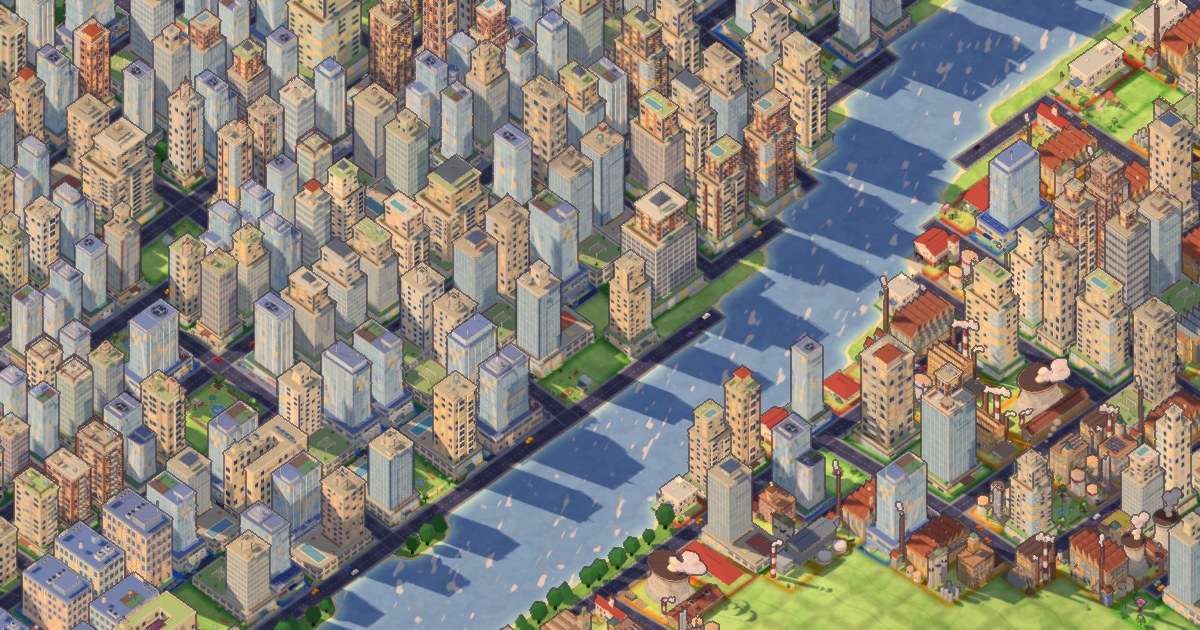 Permit PendingPermit PendingBuild the city of your dreams. Subject to approval. A free city builder about zoning, hearings, lawsuits and reelection.
The Future of CSS (joshwcomeau.com)
 www.joshwcomeau.comThe Future of CSS ✨ • Josh W. ComeauEvery year, browser vendors collaborate via the Interop project to synchronize their efforts on new HTML/CSS/JS features. This year, there’s a ton of super exciting features being considered! In this blog post, we’ll explore the CSS of the future, to get a glimpse of what we’ll soon be able to do.
Non-techie here: Is the internet going to shut down tomorrow because of the PHP vulnerability?
I'm sorry. I don't understand what the problem is and how it will affect people.
It's been discussed at length the extent to which Big Tech search engines/indexers are basically garbage at this point. Even using a wrapper like Duckduckgo, which re-arranges the results from a Google + Bing search, the usefulness of these tools is really in decline compared to how well they *used to work* (that is to say, we know for a fact that a better quality is possible on a technical level!)
It's been of course noted that the feasibility of running your own web indexer is simply too high of a bar for typical folks to clear. The web is literally just too big. There's too many links, too many pages, and all too much text to store in a cache. Not even to mention the work required to keep it up to date by doing regular crawling.
So, what about a search engine that only aims at a portion of the web? When we remove all of the big players like social media (Reddit, Twitter, etc), large forums (StackOverflow, etc), major wikis (Wikipedia, fandom wiki, etc), and large news outlets (The New York Times, AP News, etc) -- what's left?
Say we let W be the set of all pages on the web. We know that len(W) is too big to store on something that isn't a giant datacenter. What about storing (W - M), the set of all pages *minus* all the pages from major web domains (as discussed above)? How big is len(W - M)? Is it reasonable, or would you have to truncate even further, taking only a subset of (W - M)?
🧵️ (1/2)
#webSearch #search #web #indieWeb #smallWeb #marginalia #google #bing #yandex #openSource
It's been pretty busy for the past few weeks, but I got a post submitted on the site over the weekend. Nothing serious, but still glad I took the time. Having a #neocities mirror is pretty cool as well, because I get a base level of traffic to my site on update. The people are very nice and supportive as well. If you have a site that's static, it's a good choice!
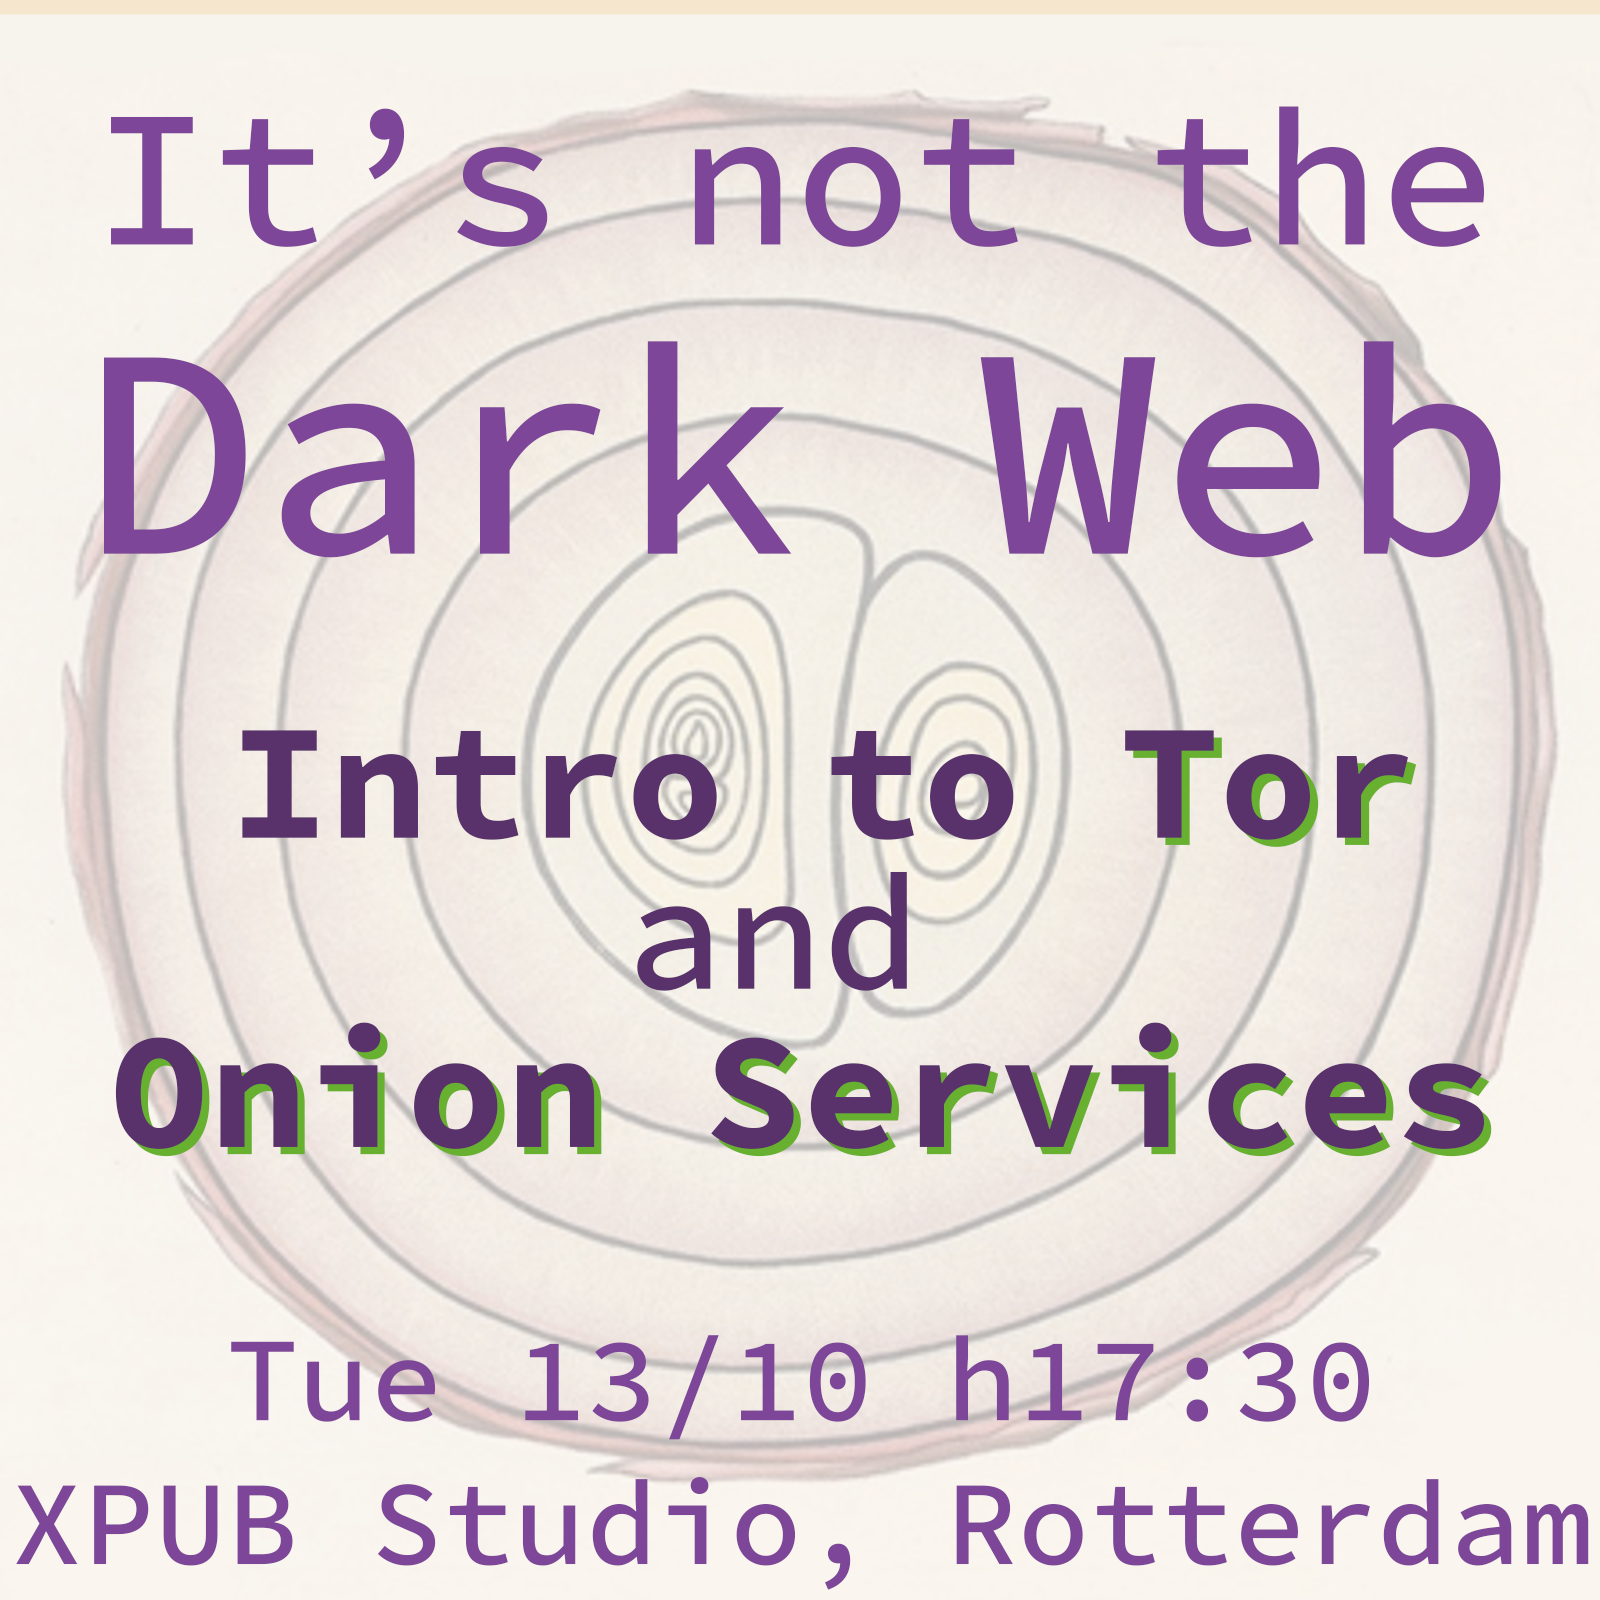
Silvio and @ggus from @torproject are coming to @xpub to host an introduction to Tor and Onion Services.
🧅 They will be sharing the most critical issues of the Internet at all its layers, and how Tor addresses them.
🗓️ Tuesday 13 October 2026 at h17:30 in the XPUB Studio, Rotterdam.
ℹ️ All information and details here.
#Rotterdam #Tor #OnionServices #Onion #DarkWeb #Web #Internet #workshop #intro #101 #TorProject #browser